一位用户刚刚向我指出了这个问题:
Misaje 语言(和喀麦隆的大多数语言一样)在元音上带有声调符号(更准确地说,是语法标记)。
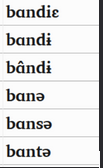
当按单词对单词列表进行排序时,效果非常好。它会忽略声调标记对单词进行排序,当有多个单词字母相同时,会将这些单词垂直排列在一起:
当按单词末尾(End of word)对单词列表进行排序时,带有标记的元音突然出现在不属于字母表的字母(r, x)下方,并按照标记的顺序排列(先是所有低声调,然后是所有高声调,……):
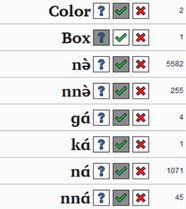
该语言使用分解的变音符号,因此如果考虑变音符号,第二张截图中的排序是完全合理的。不幸的是,“在过滤单词列表时忽略变音符号”(Ignore diacritics when filtering wordlist)对排序没有影响,只对过滤有效。它似乎应该影响排序。
字母表的配置如下:
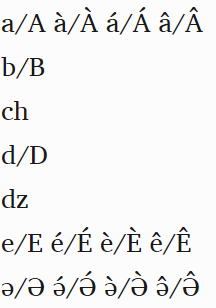
A user just alerted me to this:
The Misaje languages have (as most languages in Cameroon) tone marks on vowels (grammatical marks to be more precise).
When you sort the wordlist by word, this works very nicely. It sorts the words regardless of tone marking, and then when there are multiple words with the same letters it will put these below each other:
When you sort the wordlist by End or word, the vowels with markings suddenly appear even under the letters that are not part of the alphabet (r, x), in the order of markings (first all low tones, then all high tones, …):
The language uses decomposed diacritics, so the ordering in the second screenshot makes perfect sense if it is taking diacritics into account. Unfortunately, “Ignore diacritics when filtering wordlist” has no effect on sorting, only filtering. It seems like it should affect the sorting.
This is how the alphabet is configured:
机器翻译自 English








