मैं एक RTL प्रोजेक्ट के LTR लिप्यंतरण (transliteration) पर काम कर रहा हूँ। किसी कारणवश, PDF निर्यात में अंकों के आसपास विराम चिह्नों की दिशा कभी-कभी उलट जाती है।
Paratext में सब कुछ ठीक दिखता है, जैसे:
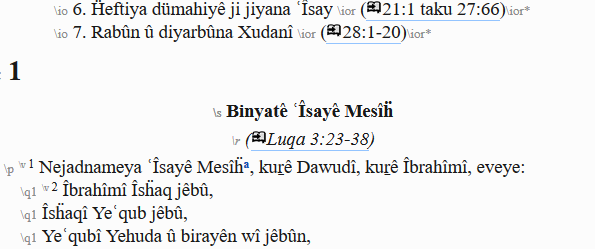
लेकिन PDF निर्यात में यह इस तरह दिखता है:
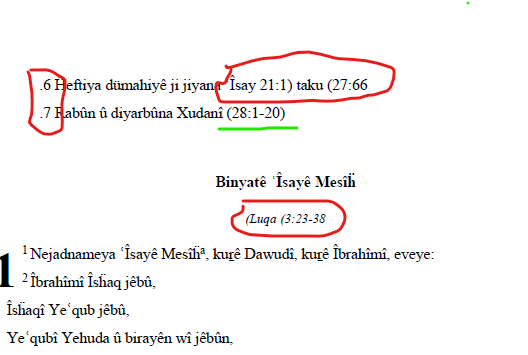
कभी-कभी यह ठीक होता है, लेकिन अक्सर यह बहुत गड़बड़ दिखता है।
मुझे लगा कि शायद RTL स्रोत पाठ से कुछ अदृश्य दिशा चिह्न (direction markers) अभी भी बचे हुए हैं, लेकिन मैंने U+200E और U+200F के लिए खोज की है; वे वहाँ नहीं हैं। अंक और विराम चिह्न मानक एन्कोडिंग के प्रतीत होते हैं।
मैं यह व्यवहार “साधारण” LTR प्रोजेक्ट्स में नहीं देखता, केवल लिप्यंतरित (transliterated) प्रोजेक्ट्स में। क्या कोई सेटिंग है जो स्रोत प्रोजेक्ट से बची हुई हो जिसे मुझे बदलना होगा?
I am working on an LTR transliteration of an RTL project. For some reason, the directionality of punctuation around numerals in a PDF export is sometimes reversed.
Everything looks fine in Paratext, e.g.:
But in the PDF export it looks like this:
Sometimes it is okay, but it is often very messy.
I thought there might be some invisible direction markers from the RTL source text still hanging around, but I have searched for U+200E and U+200F; they are not there. The numerals and punctuation seem to be standard encodings.
I do not observe this behavior in “plain” LTR projects, just transliterated ones. Is there some setting that might be left over from the source project that I need to change?
English से मशीन-अनुवादित








