鑑於各團隊開始使用 Glyssen 對新約文本進行預處理,以識別文本中的每位說話者,從而進行戲劇化錄音,我想知道是否值得順勢利用這項工作,在 Paratext 專案中自動標記耶穌的話語 \wj … \wj*。
Glyssen 會生成一個包含所需數據的 Excel 檔案,其外觀如下:
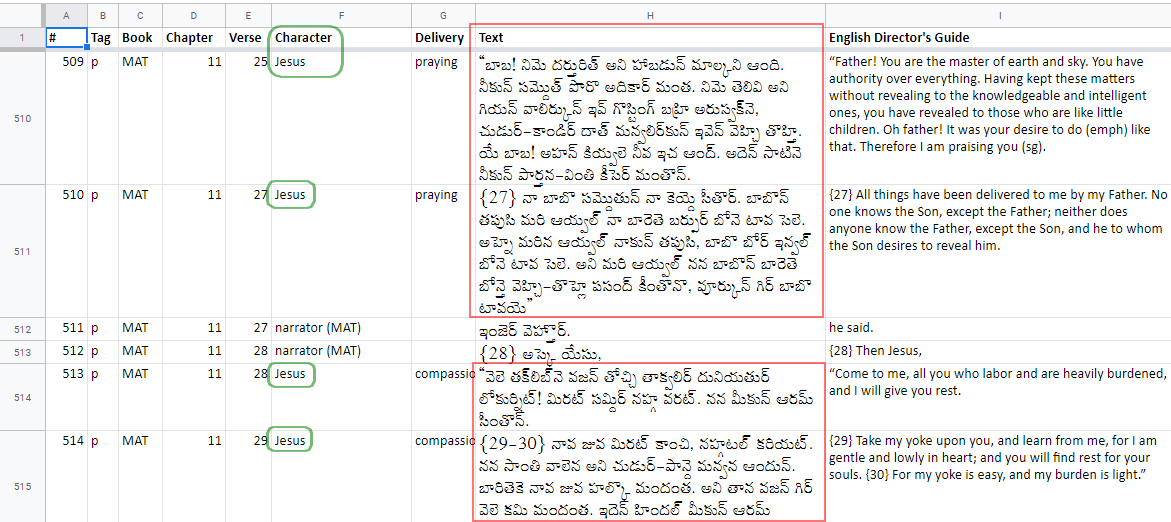
image.png1171×522 59.8 KB
因此,生成一個腳本來查找文本中的這些位置並用 \wj … 標記 …\wj* 包裹它們應該相對容易。
我自己嘗試了一些簡單的方法,使用幾個生成的 CC 表格,成功標記了 1901 處耶穌話語中的 88%。然而,這仍然留下了 200 多處需要我手動進入並修復的地方。對這個結果不滿意,並希望通過自動化、完整且更防錯的方式來節省他人未來的時間,我考慮創建一個自訂腳本(使用 Python),以便直接在 Paratext 內部執行此任務。
使用 CC 方法時,大多數「失敗」的情況是因為其他標記(如 \w angel|angels\w* 或 \f 腳註以及 \x 交叉引用)嵌入在要搜索的文本中。我有一些想法,可以通過使用正則表達式(以及搜索字符串的開始和結束位置,而不是整個字符串等)來規避這些問題,但這超出了 CC 的範疇,需要使用一些 Python 代碼才能實現。
但是,在我嘗試創建自訂腳本來執行此操作之前,我想知道是否有人已經做了類似的事情。我不想像重新發明輪子!查看隨 Paratext 附帶的示例腳本,我看到最接近的是 DRM 的 TransferParallelPassageRefs.py。
是否有人有類似的功能,或者是否有其他人在使用 ScriptureObjects 進行 Python 編程方面更有天賦,能夠比我做得更好?如果這有幫助,我願意撰寫偽代碼。我也願意學習並與其他人合作處理此事……
Given that teams are starting to use Glyssen to pre-process their NT texts to identify each speaker in the text for a dramatized recording, I wondered whether it would be worth piggy-backing on that work to AUTOMATICALLY mark up the Words of Jesus \wj … \wj* in the Paratext project.
Glyssen produces an Excel file with the needed data in it, which looks like this:
image.png1171×522 59.8 KB
So it should be relatively easy to generate a script to find these places in the text and wrap them with the \wj … markup …\wj*
I tried something simple myself with a couple of generated CC tables, and managed to get 88% of the 1901 occurrences of the words of Jesus marked up successfully. However, this still leaves 200+ places where I would need to go in and fix it manually. Being unsatisfied with this result, and wanting to save others time in the future by making it automated, complete and more foolproof, I wondered about creating a Custom Script (in Python) that could do this task directly from within Paratext.
Most of the “failed” cases with the CC method are because of other markup like \w angel|angels\w* or \f footnotes and \x cross-references being embedded within the text being searched for. I’ve got some ideas about how to get around those using Regular Expressions (and searching for the start and end of strings rather than the whole string, etc.) but that is beyond CC and would need to use some Python code to make it possible.
BUT, before I attempt to make a Custom Script to do this, I’m wondering if anyone else has done something similar already. I don’t want to re-invent the wheel! Looking at the sample scripts shipped with Paratext, the closest thing I see is TransferParallelPassageRefs.py by DRM.
Does anyone else have something similar, or is anyone else more gifted at Python programming with ScriptureObjects who could pull this together better than I ever could? I’m willing to write the pseudo code if that’s helpful. And I’m willing to learn and work with someone else on this…
機器翻譯自 English








