謝謝 Dan 提出這個好問題。歡迎加入社群!
我們不希望人們在排版/製版過程中手動編輯 USFM 檔案,有很多很好的理由。因此,顯示「已處理 USFM」(processed USFM)的檢視器(Viewer)主要用於診斷目的。它顯示了由於應用程式中多種設定而進行的所有預處理的最終結果,這些資料會被傳入製版程式(XeTeX)。
然而,有個好消息:已經有一種機制可以完全透過巧妙的搜尋與取代規則(稱為正規表示式,或 RegEx)來自動化您要求的操作。在「進階」(advanced)標籤頁中,有一個選項可以啟用 PrintDraftChanges.txt 以將其應用於文字。
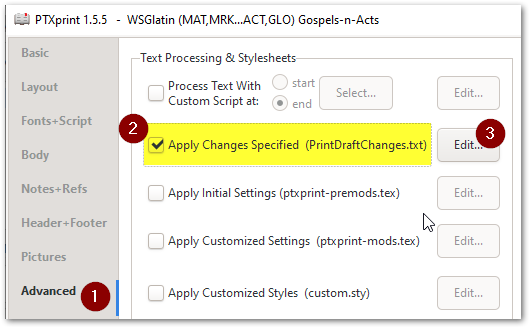
一旦您點擊了「編輯」(Edit),您可能會看到一個包含許多規則的檔案,或者編輯器中可能只有一個空檔案。
# A rule in this PrintDraftChange.txt file uses this syntax:
"Find what" > "Replace with"
因此,對於這個「移除重複標題」的任務,您需要添加一個正規表示式規則,看起來可能像這樣:
"\\rem (.+?)\r?\n\\s \1\r?\n" > "\\s \1\r\n"
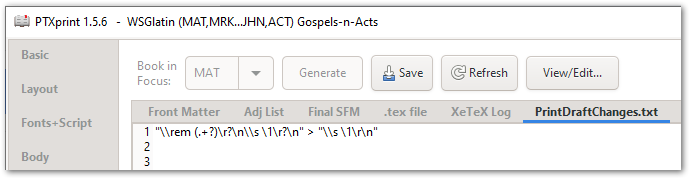
如果我上面提供的內容不完全符合您的需求,請按需調整(例如,將 \rem 替換為您文字中使用的任何標記)。我強烈建議使用像 regex101.com 這樣的網站來完善您的表示式,並在資料的一個小子集上測試您的搜尋和替換字串,直到它運作為止。
希望這能幫到您,但如果您仍然遇到困難,請尋求進一步的說明。
Thanks Dan for your good question. Welcome to the community!
There are many good reasons why we DON’T want people to be editing the USFM files manually during the layout/typesetting process, so the Viewer that shows you the “processed USFM” which gets fed into the typesetting program (XeTeX) is primarily there for diagnostic purposes. It shows the end result of all the pre-processing that has taken place due to the multitude of settings in the App.
HOWEVER, there is good news: There already is a mechanism to do exactly what you’re asking for by automating it completely through clever find and replace rules (called Regular Expressions, or RegEx). On the advanced tab is an option to enable PrintDraftChanges.txt to be applied to the text.
Once you’ve clicked on Edit, you might see a file with a bunch of rules in it, or there may just be an empty file in the editor.
# A rule in this PrintDraftChange.txt file uses this syntax:
"Find what" > "Replace with"
So for this “strip out the duplicate headings” task, you’ll need to add a RegEx rule which will look something like this:
"\\rem (.+?)\r?\n\\s \1\r?\n" > "\\s \1\r\n"
If what I have above doesn’t quite match your needs, then adjust it as needed (for example replace \rem with whatever marker you have in your text). I highly recommend using a site like regex101.com to refine your expression, and test out your Find and Substitution strings on a small subset of your data until it works.
I hope this helps, but if you’re still stranded, please ask for further clarification.
機器翻譯自 English








