0 票
1.2k 次瀏覽

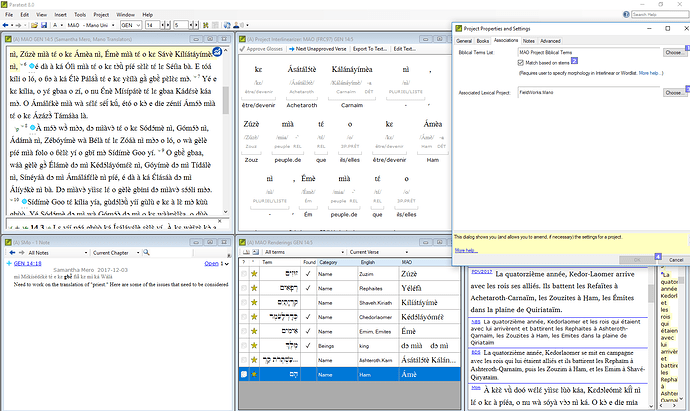
I am trying to use the Match Based on Stems tool in my project, but it does not seem to be working. I have “Match based on stems” checked in Project Properties and Settings. You can see from the screenshot that I have identified the morphology for the name “Ham” (the city) in the interlinear, and that in this verse it has a determiner on it. In the Renderings tool, I have listed only the stem “Ham.” It is my understanding that this should be approved because “Ham” is in the morphology. However, you can see that it is not approved, nor are any of the other city names in the verse because they all have determiners.

If I uncheck “Match based on stems,” all of these will be approved because the determiner is listed in my list of affixes. So, that method works. However, I would prefer to use match based on stems, as it should be more accurate, and I have to make an interlinear for the consultant anyway, so there is really no more work involved. Can anyone help me get this to work?
舊文章 - 以原文顯示
Paratext 由 (155 點) 提出 | 1.2k 次瀏覽

10 個回答

0 票
最佳回答

anon044949,

Thank you for your input. That’s the way the process is supposed to work. But it’s not working in my project for some reason. I shouldn’t need to approve the morphology in both the Wordlist and the Interlinear. Approving in one should automatically approve in the other. And it does. Here is a screenshot of my Wordlist showing Ámèa as correctly parsed:

But for some reason, Renderings still won’t approve the root “Ámè.”

舊文章 - 以原文顯示
由 (155 點) 提出

anon807810, this may not have anything to do with your problem, but I think it’s worth a mention. I see you have diacritics. Is your project Normalized or not (go to Project Properties and Settings, Advanced Tab, Normalization)? If not, are these diacritics, the accents on á, etc, decomposed characters (i.e. a sequence of two characters, the a and the acute accent, in Unicode)? If they are, then it may be that this issue is causing the Match Based on Stems not to work? You are welcome to contact me off list, and we could discuss this further.

舊文章 - 以原文顯示

anon807810,

You are correct that one can use either the word list tool or the interlinearizer. I prefer the word list tool so that I can see all the words with the same root/stem. It is your choice of course. Paratext often has more than one way to do things to suit a wider range of needs.

舊文章 - 以原文顯示
0 票

Looks like a bug in Paratext. Could you use Help > Report a problem to report the issue to us?

舊文章 - 以原文顯示
由 [Expert]
(16.7k 點) 提出
0 票

OK, I have done so. Has anyone else reported this problem or is it just a problem with my copy?

舊文章 - 以原文顯示
由 (155 點) 提出
0 票

I don’t know of any other reports, but I’m also not sure that many projects use the feature since it didn’t work well in PT7.
Since this is blocking your work and I suspect it to be an easy fix, it should be a high priority for us to fix it.

Since I, as an English-only speaker, have a hard time seeing subtle differences in non-English text, can you confirm that all three names shown in your screenshot should be matching?

舊文章 - 以原文顯示
由 [Expert]
(16.7k 點) 提出

已重新顯示
0 票

You mean the three names that aren’t checked as “found”? Yes, they should all be checked. In the Interlinearizer, you can see the word Ámèa and that this is made up of the name Ámè plus the determiner -a. Then, at the bottom of the Renderings box, Ámè is listed as the rendering for the name Ham. So this should be checked, but it’s not. The exact same thing is happening for the other two names. They all have a determiner on them.

舊文章 - 以原文顯示
由 (155 點) 提出
0 票

I have gotten this to work and made some training material on this. I will review it and try and help you tomorrow.

舊文章 - 以原文顯示
由 [Expert]
(2.9k 點) 提出

Ok, Sorry but I needed to review the process. I had not thought about it for a while. I think the step you are missing is to go to the Word list tool, click on view morphology and begin marking the morphemes. Only word parses that are approved, i.e. black, will be used by the project interlinearizer. The red parses are only guesses and will not be used by the project interlinearizer. Below is a screen shot of the Word list tool with the morphology column visible. I have a video that shows this method and three others to teach the Biblical terms tool the morphemes of a language if you need more help.

After you have approved the morphemes in either the word list tool or the project interlinearizer, then you will have to go to the Biblical terms tool and approve the stem/root for each term. In the case shown in the above screen capture, I approved “veny” as the rendering of “raise/ἐγείρω”. Paratext does the rest and approves all the renderings for ἐγείρω with the root “veny”!

舊文章 - 以原文顯示
0 票

The problem was deep inside Paratext (not a problem with their project). It was doing a cased compare with the stem and one was uppercased and the other was lowercased. This has been fixed and should be in the next update.

舊文章 - 以原文顯示
由 [Expert]
(16.7k 點) 提出

If the problem is related to the ability to ignore case, I admit that when I have used the stem matching, I never tried cases where case would be an issue. My special area of research is in Bantu languages where mixed capitalization is often allowed in the orthography. Thank you anon807810 for finding this bug.

舊文章 - 以原文顯示
0 票

Thanks for your help, everyone.
anon758749: The project normalization is decomposed, yes. I changed this when PT8 came out to fix a problem with the Wordlist listing the same word multiple times. I hope I didn’t fix one problem only to create another.

anon291708: I hope you’re right that this will fix the problem, though I don’t understand why it would. Nothing was lower case. Ámè is a proper name and is always upper case, both in the text and the Renderings. But I know nothing of programing, so I probably just don’t understand what you mean.

anon807810

舊文章 - 以原文顯示
由 (155 點) 提出

This was deep in the code where it was doing a comparison to the lexicon entry. Lexicon entries are stored all lowercase for the interlinear, internally. In this particular instance, we forgot that fact and did a direct compare instead of a caseless compare.

舊文章 - 以原文顯示

Gotcha! (I think.) Anyway, I will look forward to the next update.

舊文章 - 以原文顯示
0 票

The fix should be in 8.0.100.67 which should be going out to everyone soon.

舊文章 - 以原文顯示
由 [Expert]
(16.7k 點) 提出

Very great that you could diagnose the problem and fix it. Sometimes bugs that only show up in very specific and rare situations are hard to interpret.

舊文章 - 以原文顯示
0 票

4 posts were split to a new topic: Biblical Term counts not updating

舊文章 - 以原文顯示
由 [Expert]
(16.7k 點) 提出

相關問題

0 票
1 個回答 230 次瀏覽
我正在處理一種語言,該語言中帶有前綴和後綴的詞可以透過重疊(reduplication)來表示複數 正字法中使用「-」來標記重疊 當帶有前綴和後綴的形式發生重疊時,詞表(Wordlist)似乎無法處理其形態變化 它認為整個形式都是詞幹,如 ... 不允許在後綴之後添加前綴 有沒有人知道該如何處理這個問題?還是這超出了 Paratext 目前的功能範圍?
fhardison8588 111 提出 已提問 12月 12, 2022
0 票
1 個回答 186 次瀏覽
您好, 我代為向一位同事詢問,他在專案中遇到 Interlinearizer 的奇怪問題 他已為幾卷書完成了大量的對照翻譯工作,然而,當他想要在「任務與進度」(Assignments and Progress)中將該卷書的狀態標記為「完成 ... 否我們有設定錯誤,導致 Interlinearizer 的檔案未與「任務與進度」視窗連結?任何協助都將不勝感激
KmSilvey 109 提出 已提問 11月 14, 2022
0 票
2 個回答 348 次瀏覽
我希望確保每一節經文都至少由團隊中的兩位成員核准 過去,我們使用自訂軟體(非 Paratext),該軟體允許使用者登入並標記他們核准的經節,因此我們可以自信地說:「這本書中的每一節經文都至少由團隊中的兩個人核准 」核准標記僅適用 ... 事了 ) 就我所知,Paratext 不提供此功能,但也許它其實有,只是我沒注意到 也許有辦法利用回譯功能來實現這一點嗎?
bit 495 提出 已提問 4月 19, 2022
0 票
4 個回答 2.0k 次瀏覽
在這裡我得坦白,我對希伯來語知之甚少,但我正在嘗試弄清楚如何找到一個我認為應該出現在「Biblical Terms」(聖經術語)工具中的內容 Ezk. 14:20 中有單詞 בְצִדְקָתָ֖ם,在「Source Language Text」(原文文 ... 問題,但也許我的方法不對?我搜尋了 Vimeo 上的影片,想找一些幫助,但沒找到任何相關內容
Paul 642 提出 已提問 2月 3, 2021
0 票
4 個回答 746 次瀏覽
這個專案使用基於詞根(stem-based)的設定,已經順利運行數週了 這種語言會產生許多複合詞 它們可以是名詞 動詞 形容詞以及「更複雜情況」的任意組合 當然,這些元素結合的方式有「規則」可循,邏輯清晰,且每 ... 想像一種語言,他們說 overmother ,其中 mother 是意為母親的詞根,而 over 是意為 μέγας 的前綴 )
Tim 934 提出 已提問 4月 24, 2019
Welcome to Support Bible, where you can ask questions and receive answers from other members of the community.
And let us consider how we may spur one another on toward love and good deeds, not giving up meeting together, as some are in the habit of doing, but encouraging one another—and all the more as you see the Day approaching.
Hebrews 10:24-25
3,052 個問題
6,011 個回答
5,677 則評論
2,032 位使用者