Я встречал случаи, когда автоматическая разметка записей глоссария размечает ВТОРОЕ вхождение слова в стихе, а не первое (хотя я выбрал опцию «разметить первое вхождение в разделе»). Например, в этом стихе «Masi» — это эквивалент, который программа находит:
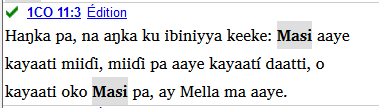
Но она размечает ВТОРОЕ вхождение с помощью \w … \w*, а не первое. Это баг?
I’ve seen some cases where the automatic glossary entry marking is marking the SECOND occurrence in a verse rather than the first one (when I have selected mark the first occurrence in the section). For example in this verse, “Masi” is the equivalent that it is finding:
But it marked the SECOND occurrence with \w … \w* rather than the first. Is that a bug?
Переведено машиной с языка English